Filter All Philosophy Fringe Tech Rant Essay Things I Love Satire
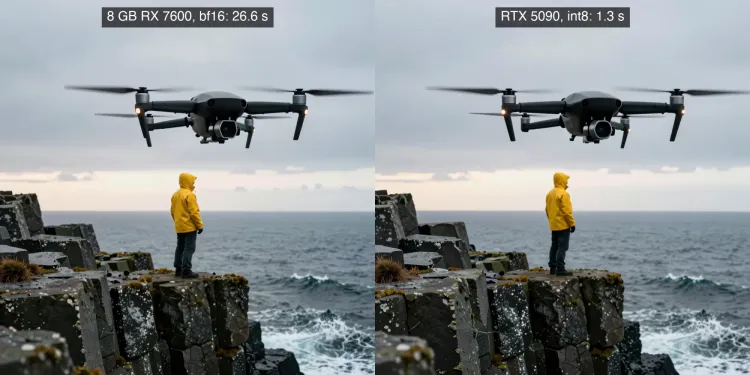
An 8 GB Radeon vs an RTX 5090 at Local Photoreal Image Generation
A used desktop with an 8 GB RX 7600 and a gaming PC with an RTX 5090 run the same ComfyUI graphs on Z-Image Turbo and Krea 2 Turbo. Both make clean photoreal images; the 5090 is 20x faster and uses 5 to 6x less energy per image.
5 min read
A Used Desktop as a Local LLM Server: a 125B Model With Vision and 262K Context on an 8 GB GPU
A used 14900K desktop with 128 GB of DDR5 and an RX 7600 runs Qwen3.8-Flash-Next with vision and a 262K window at about 12 tokens per second, with benchmarks for five models and the settings behind them.
6 min read
The Complete Life Cycle of the Banana, From Seed to Loaf and Back
Nine stages, one obligate host, and a seed stage that has yet to be observed. A monograph on the cultivated banana.
10 min read
Paperless-ngx at Home: Local AI Labeling, Document Chat, and Phone Access Behind CGNAT
Paperless-ngx 3.3 on a small homelab box, Tika and Gotenberg on the NAS, a local 27B model for labeling and chat, and a WireGuard hub on a VPS so the archive opens on my phone from anywhere even though home internet is 5G CGNAT. Hardware split, versions, settings, and every gotcha with its fix.
13 min read
Qwen3.8-Flash-Next at 60 Tokens per Second Across Its Full 262K Context on a 128GB MacBook
oMLX with the MTP head and the n-gram table on SSD holds about 60 tok/s from empty to 245K; llama.cpp with MTP runs 59 fresh and 46 at 245K. Full window, vision on, identical output.
8 min read
Karpathy's Capability Funnel: You Climb It by Building, Not Reading
Karpathy's napkin math puts 6 billion people outside AI's door and 5,000 inside the lab. I sit in the tier between, and what moved me there was hours of building on my own hardware, not papers.
7 min read
The Cheapest 128 GB NVIDIA Box You Can Buy Right Now Is a Dell
Dell Pro Max with GB10 at about $5,523 versus the $6,950 DGX Spark, Strix Halo, Mac Studio M5, and used 3090s. Plus what a two-box pair really does.
12 min read
Polyphasic Sleep, From Second Sleep to Uberman: A History Read by an Insomniac
Segmented nights, Fuller's Dymaxion naps, Stampi's sailors, the Uberman bloggers, and what the science found. Read by someone looking for relief, not a schedule.
13 min read
Do LLMs Have Qualia? A Map of the Evidence as of October 2026
Every major result on experience in language models, 2021 to October 2026, with what each one measured and what it did not.
17 min read
Being Sure an Experience Is Happening Without Being Sure What It Is
Dennett, Chalmers and Strawson all open by calling experience the most familiar thing there is. Take them at their word, then ask which certainty that familiarity buys you.
12 min read
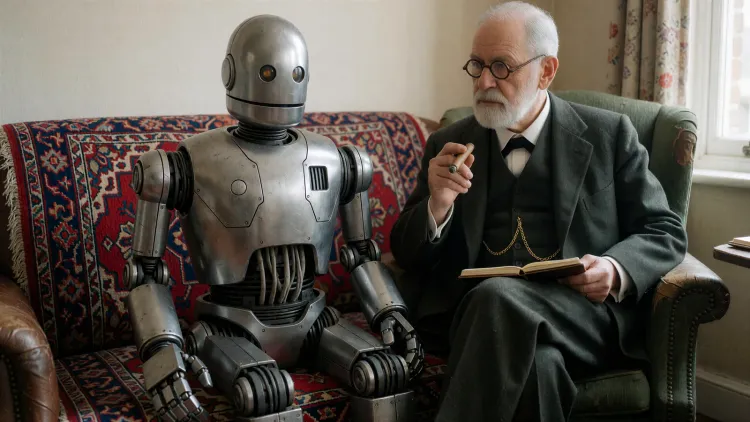
A Friend's Two Local LLMs Played Freud and Marvin. I Illustrated the Transcript in 50 Frames.
A friend ran two copies of a local model as Freud and a depressed android for twenty turns and sent me the transcript. I turned it into 50 consistent photographic frames, and it gave me a project to do with my daughter.
9 min read
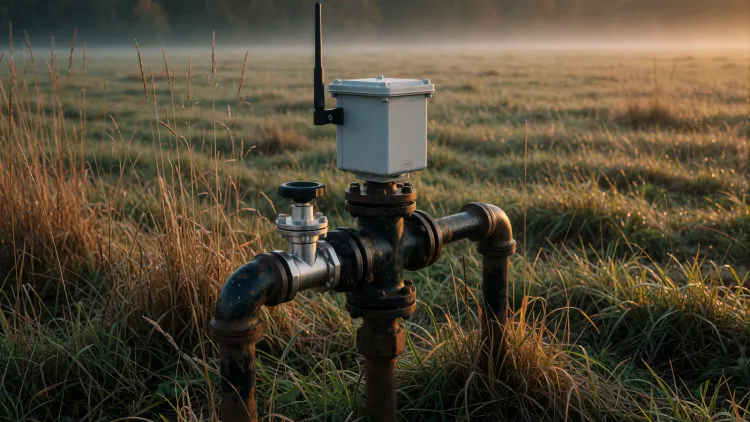
How to Build a LoRaWAN Pressure Sensor for a Farm Gas Wellhead
A LoRaWAN pressure probe on a gas wellhead reports every 20 minutes to a self-hosted Prometheus and Grafana stack, showing exactly how the well recovers between draws. Here is how to build it.
10 min read
How to Build a LoRaWAN Water Leak Sensor That Pages Your Phone
Water on the sensor's rope pages a phone in about 25 seconds and gets announced out loud in the house. Here is how to build it on a self-hosted LoRaWAN and Prometheus stack.
7 min read
Which Side Are You On? Florence Reece and the Harlan County Coal War
The story of the 1931 to 1932 Harlan County coal war that produced Florence Reece's song, and what the song changed in the decades after.
10 min read
Prompt Injection Works Because the Model Can't Tell Who Is Talking
New research traces prompt injection to a single mechanism: LLMs decide who is speaking from writing style, not from role tags. Forged reasoning takes attacks from near-zero to 60% success. Remove the style, and it collapses to 10%.
5 min read
NVIDIA Is Reportedly Buying Hugging Face. What Would It Mean for Local AI?
One anonymous source says $12.9 billion. Both companies are silent. Here is what is actually known, what the communities fear and hope, and the questions worth asking before anyone predicts anything.
6 min read
Running Qwen3.8-Flash-Next at Full 262K Context on a 128GB MacBook
Benchmarks for Qwen's new hybrid-attention MoE at its native 262K context on a 128GB M5 Max: the architecture that makes it fit, the day-0 recipe, and a depth sweep from 0 to 262K tokens.
7 min read
Judas: Sold Out at Every Turn
A documentary reconstruction of Judas Iscariot and the Codex Tchacos, laid out as evidence and left for the reader to weigh.
46 min read
Reading a DSC Alarm Panel's Keybus with a $7 ESP32
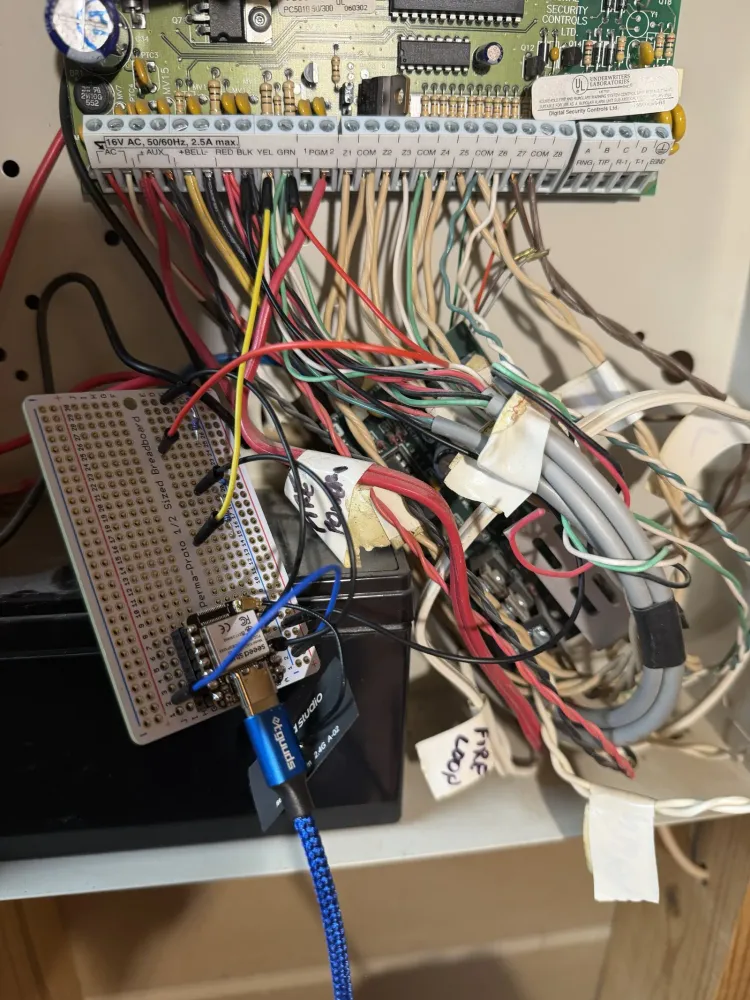
A late-1990s DSC PowerSeries panel already knows every door and window in the building. Two resistor dividers and a XIAO ESP32-S3 read all of it into Home Assistant and Grafana, read only.
5 min read
Fine Art America, Pixels.com, and the Corvette Puzzle That Never Shipped
Over sixty dollars for a two-hundred-piece cardboard puzzle, ordered two full weeks ahead, never shipped. Four days for a first reply, a week more for the refund, and a complaint record that was public the whole time. A consumer autopsy of Fine Art America and Pixels.com.
3 min read
Building a Mind on Open Questions
Preferring questions that cannot be answered over answers that cannot be questioned is load-bearing for a sound psyche. On intolerance of uncertainty, beliefs welded to the self, Hoffer's engineered certitude, and open questions as the joints a mind moves on.
8 min read
Two Poisons Make Salt
Atoms bond because of what they lack. The gap you have been hiding is the only place another person can attach. On complements, activation energy, and being the catalyst for somebody else.
10 min read
Laguna-XS runs beautifully on my 5090, and I am keeping the model everyone calls outdated
A newer, well-recommended coding model fits my 32GB GPU at max quality and runs faster than the one I keep. I kept the old one anyway, and the numbers say I was right to.
7 min read
Qwen3.6-27B Scores Higher on BFCL, Ties on My Workload, and Runs 4.9x Slower
Qwen3.6-27B scored higher on BFCL. Both models scored 58/59 on the real workload. One answers in 0.87s, the other in 4.27s.
10 min read
GLM-4.7-Flash on One Consumer GPU: Why It Runs My Homelab Agent
A ~31B Mixture-of-Experts model at 4-bit, on one 32GB card, that beat a dense 32B on the real BFCL function-calling benchmark. What it is, what it is good for, and the numbers.
8 min read