Filter All Philosophy Fringe Tech Rant Essay Things I Love
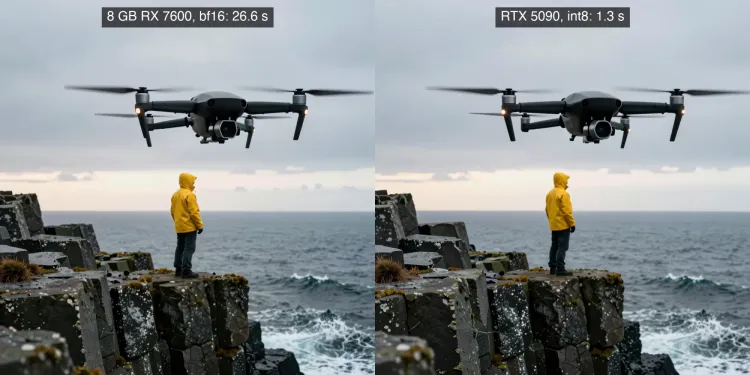
An 8 GB Radeon vs an RTX 5090 at Local Photoreal Image Generation
A used desktop with an 8 GB RX 7600 and a gaming PC with an RTX 5090 run the same ComfyUI graphs on Z-Image Turbo and Krea 2 Turbo. Both make clean photoreal images; the 5090 is 20x faster and uses 5 to 6x less energy per image.
5 min read
A Used Desktop as a Local LLM Server: a 125B Model With Vision and 262K Context on an 8 GB GPU
A used 14900K desktop with 128 GB of DDR5 and an RX 7600 runs Qwen3.8-Flash-Next with vision and a 262K window at about 12 tokens per second, with benchmarks for five models and the settings behind them.
6 min read
Laguna-XS runs beautifully on my 5090, and I am keeping the model everyone calls outdated
A newer, well-recommended coding model fits my 32GB GPU at max quality and runs faster than the one I keep. I kept the old one anyway, and the numbers say I was right to.
7 min read
Qwen3.6-27B Scores Higher on BFCL, Ties on My Workload, and Runs 4.9x Slower
Qwen3.6-27B scored higher on BFCL. Both models scored 58/59 on the real workload. One answers in 0.87s, the other in 4.27s.
10 min read
GLM-4.7-Flash on One Consumer GPU: Why It Runs My Homelab Agent
A ~31B Mixture-of-Experts model at 4-bit, on one 32GB card, that beat a dense 32B on the real BFCL function-calling benchmark. What it is, what it is good for, and the numbers.
8 min read